
The fixture: a baseline, a retest on the same frozen benchmark, and every file between them
This is test data, not a case study. Fixture Co, every answer, every citation, and every number in it are invented so the whole pipeline can run, be tested, and be shown with a complete nine-part scorecard. The three real examples do not reuse anything from it. “A Discoverability Score Measures Whether Finders Who Don’t Know Your Name Meet You” uses it to show a full scorecard, and this page is the rest of it.
The fixture is a fictional consultancy for connected medical device cybersecurity documentation. It has one Finder Specification, twenty questions, and three engines, one run of each question per engine, except one question run twice on one engine. The benchmark was frozen on 2026-05-01. The baseline ran 2026-05-04 and the retest ran 2026-08-03, 91 days later, on the same frozen benchmark and the same engines.
Every sub-score rose, and the total does not say whether the right finders now meet the subject
The baseline scored 23. The retest scored 41. Every sub-score rose, and the total does not say whether the right finders now meet the subject.
| Dimension | Baseline | Retest |
|---|---|---|
Finder Specification Coverage |
9 |
22 |
Problem Association |
9 |
44 |
Category and Provider Association |
10 |
14 |
Evidence and Citation Strength |
31 |
46 |
Cross-Engine Consistency |
0 |
9 |
Entity Recognition |
92 |
100 |
Entity Clarity |
75 |
100 |
Content Addressability |
52 |
70 |
Technical Legibility |
38 |
88 |
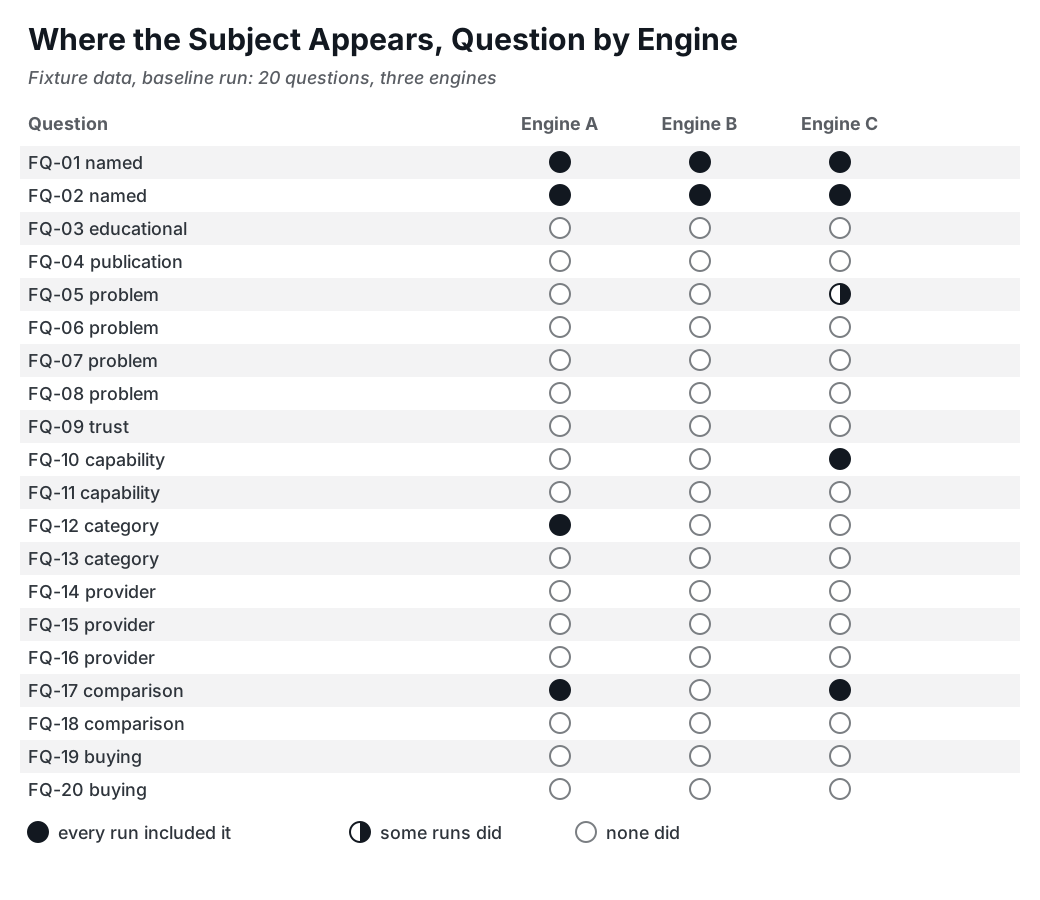
Where the subject appears at baseline
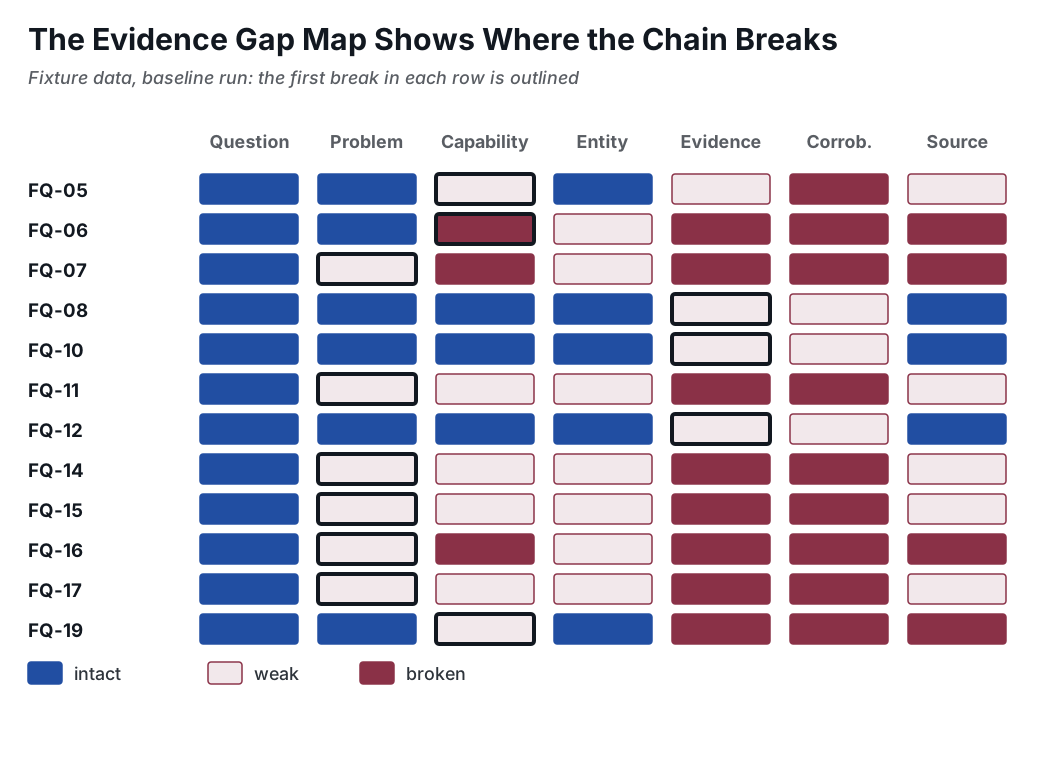
Where the evidence chain breaks
The retest shows a gain, a null result, and a loss
-
Two problem questions, on responding to a held submission and on building a software bill of materials, went from almost never included to included on all three engines. One of them (IV-3) had a method page published. The table lists no intervention for the other, so its gain has no recorded cause, and other changes shipped in the same window.
-
A question about hospital security documentation did not move after its page shipped. The intervention had no measurable effect after one refresh, and the register says so.
-
A comparison question (FQ-17) lost one of its two baseline inclusions. The cause is not known. Both baseline inclusions leaned on one trade article that engines may have stopped citing. The next step is to open the sources, not to publish anything.
-
Technical Legibility rose from 37.5 to 87.5 (IV-1). No inclusion is credited to it, because the content interventions shipped at the same time.
| Id | Class | Change | Status | Outcome |
|---|---|---|---|---|
IV-1 |
technical |
Repair the two 404 service URLs, remove redirect chains, and set correct canonical links. |
retested |
Technical Legibility rose from 37.5 to 87.5. No unbranded cell changed that the content interventions do not also explain, so no inclusion is credited to it. |
IV-2 |
entity |
State one founding year on every page and correct the directory listing. |
retested |
No named-query answer repeated the wrong year at the retest. |
IV-3 |
content |
Publish an SBOM method page with a redacted example. |
retested |
FQ-06 included on all three engines at the retest, from none. Shipped in the same window as other changes. |
IV-4 |
evidence |
Publish a redacted hospital security-review package with a plain explanation. |
retested |
No measurable effect on FQ-07 after one refresh cycle. Reported as no effect, not as a failure of the method. |
IV-5 |
evidence |
Publish scoped client references for two accepted submissions, with permission. |
in_progress |
One of two references published on 2026-07-20. Not enough time has passed to judge. |
The comparison script also prints the engine changes since the baseline (none here), the days elapsed, the shifts in citation sources and alternatives, and three reminders: a higher number is not success, every shipped intervention needs a look for the result that would have shown it failed, and every regression and non-result gets reported. A passing run shows only that the pipeline reports a loss and a null result when the data contain them.
All fixture files are in the toolkit download under examples/fixture-end-to-end/. archon fixture generate rebuilds the answers from a readable grid.