Code
The scripts, notebooks or spreadsheets that produced every table and figure. A spreadsheet counts, with its formulas left in, and a short README that says the order of the steps.

Research program
A companion executable code repository is the code that produced a paper's results, packaged so that someone else can run it and get the same numbers. It sits beside the paper and the paper's data, and each of the three points to the other two. This program asks what such a repository has to hold for a reviewer, a funder or a reader to check a result without rebuilding the whole analysis. It starts with diabetes and biomedical research, because that's where I work and where a wrong number can reach a patient, and its rules are written to work in any field.
What must a companion executable code repository contain, link to and prove for a reviewer to verify a paper's results without rebuilding the analysis?
Claim: recommendation
A published paper tells you what the researchers did and why. A data repository holds what they measured. Neither shows how the raw data turned into the numbers in the paper's tables. A companion code repository fills that gap: it holds the steps themselves, in a form a computer can run again. Add a habit of releasing new versions as new data arrives, and you get a result that anyone can rerun today and test again next year.
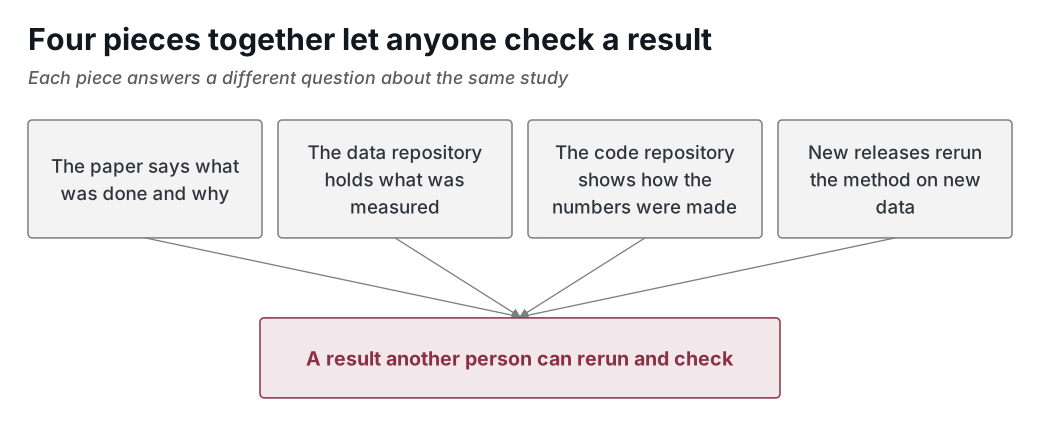
This adds to peer review and to the data repositories researchers already use. It replaces neither. The journal still publishes the paper, and the data stays where the data rules say it goes.
What would show this claim is wrong
Claim: inference
A methods section is a summary, written after the analysis ran. It can't list every rule for leaving out a patient, every unit conversion and every software version, and the result can depend on any of them. So a reviewer who wants to know whether a number is right has two choices: rebuild the analysis from the summary, which takes days nobody has, or judge whether the description sounds right. Most judge. The code that actually ran is the only complete statement of the method. When it isn't shared, a reader can believe the method but can't check it.
What would show this claim is wrong
Claim: recommendation
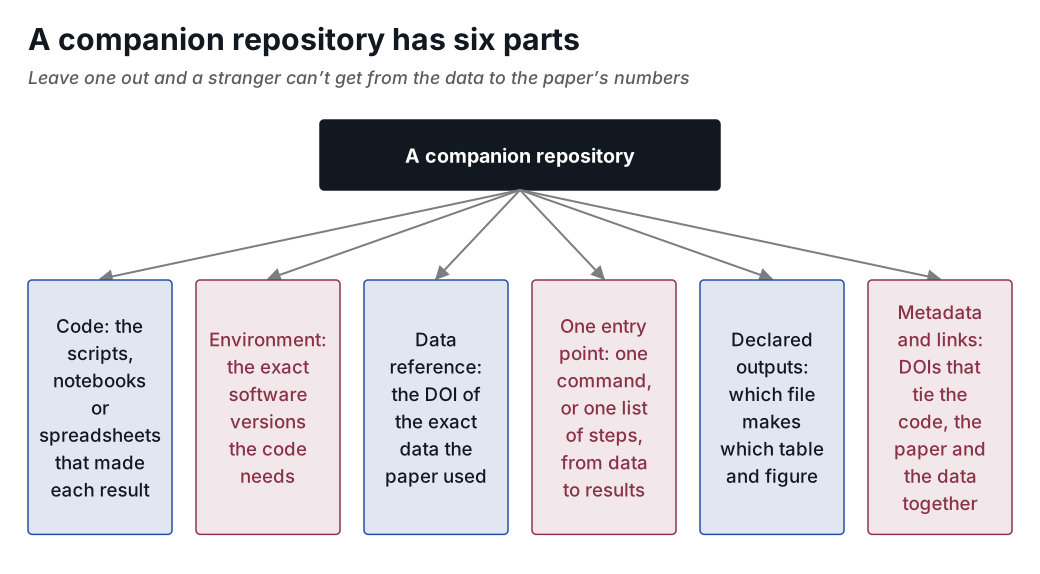
I recommend that a companion repository hold six things, and that nobody call a paper reproducible until all six are there. Each one closes a gap that otherwise stops a stranger from getting from the data to the paper's numbers.
The seven practical steps to set one up are in A companion repository takes seven steps to set up. The companion to this program has the checklists an author and a reviewer can use today.
What would show this claim is wrong
The scripts, notebooks or spreadsheets that produced every table and figure. A spreadsheet counts, with its formulas left in, and a short README that says the order of the steps.
The exact software the code needs, down to the version numbers, written in a lockfile (a list of every package and its version) or a container definition (a recipe for a clean computer with that software installed), or both.
The DOI of the exact copy of the data the paper used. A DOI (Digital Object Identifier) is a permanent address for a paper, a dataset or a software release that keeps working when websites move. Where the data may be shared, the copy itself goes in too, or a synthetic copy with the same structure.
One documented command, or one numbered list of steps, that goes from the data to every reported result.
A list of the paper's tables and figures, each matched to the file the entry point writes for it, so a rerun can be compared with the paper number by number.
A DOI for the exact release the paper cites, a second DOI that stands for every version, and links from the code to the paper and the data and back again.
Claim: recommendation
Data about individual patients, even with names and identifiers removed, belongs in a repository built to control who may see it, such as Vivli or the YODA Project, under the laws of the place the data came from. The companion repository then holds the code, the environment, the metadata and a link to the governed record. To let the code run end to end without the real data, it can also hold a synthetic copy: made-up records with the same columns and types.
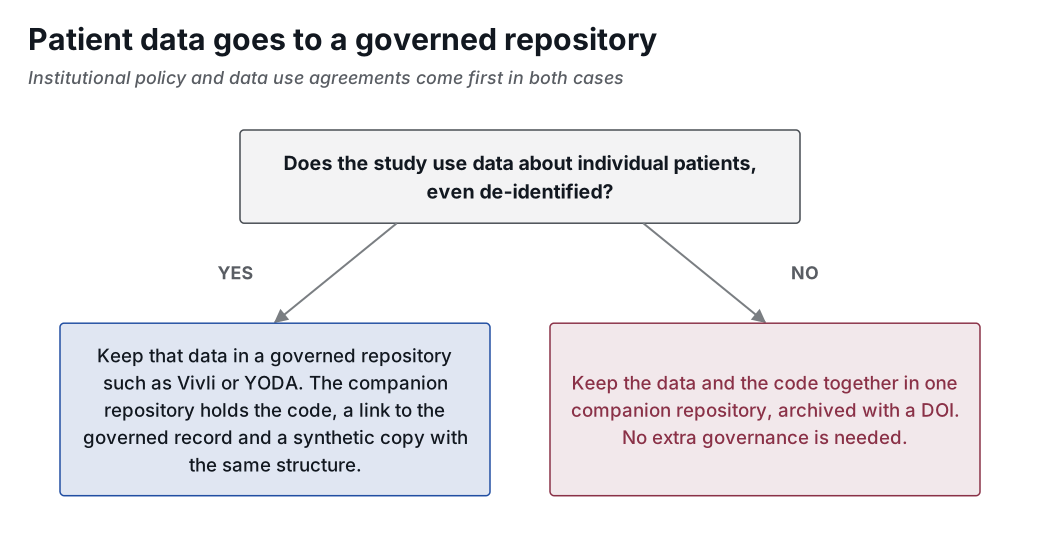
Plenty of studies have no patient-level data at all: simulations, device bench tests, analyses of published aggregates, new statistical methods. For those, the code and the data can sit together in one repository with no extra governance. Splitting only where patient data is involved puts the burden where the risk is.
Three limits apply in every case. Clinical trial data stays under the rules that already govern it, and a companion repository for a trial shares the analysis with synthetic or aggregate data. Work under an industry contract can stay private, using the approach in A private repository lets a reviewer rerun code that can't be public. And institutional policy and data use agreements come before anything this program recommends; check with your research compliance office before you share anything about sensitive or restricted data. The reasoning is in Patient data stays governed and the code goes beside the paper.
What would show this claim is wrong
Claim: recommendation
The version of the code a paper cites never changes. When new data arrives, such as real-world data from health records, registries, claims or devices, the authors can run the same method again and publish a new release. Each release gets its own DOI, and one more DOI, the concept DOI, stands for the whole line of versions. Real-world evidence is what that analysis of real-world data shows.
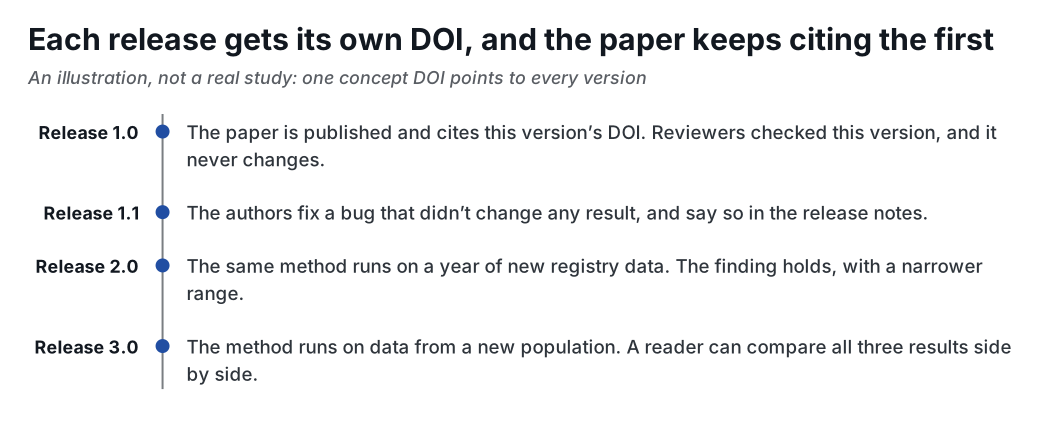
A reader can then see whether the finding still holds as evidence builds up, while the original stays exactly as the reviewers saw it. The Lovable microsite called this living evidence. I'd use that phrase only for a line of releases a person can rerun, version by version. A paper that's quietly edited after publication is the opposite of what's meant.
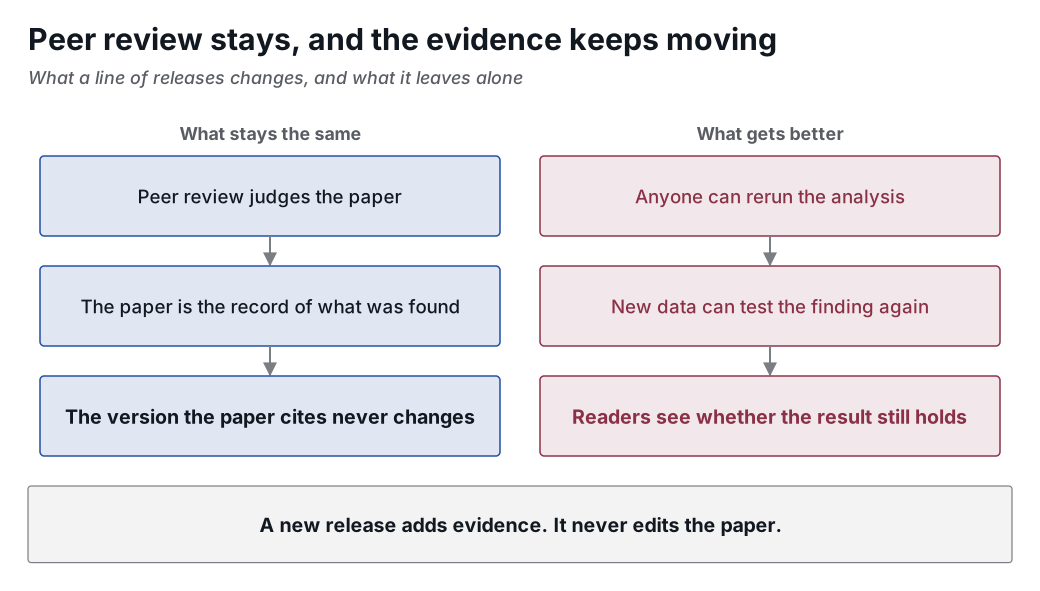
More on how this works, and on what it does to how medicine weighs evidence, is in Versioned releases keep the evidence current while the paper stays fixed and A result anyone can rerun counts for more than a famous name.
What would show this claim is wrong
Claim: recommendation
The Lovable microsite promised a new JSON Schema, a machine-readable list of the fields a file must have, for companion repositories. Standards already describe most of what's needed. CodeMeta describes software. The Citation File Format says how to cite it. RO-Crate packages code and data with the links between them. The DataCite Metadata Schema describes the DOI record. I recommend a profile: a short list of which fields of those four standards a companion repository must fill, written as a JSON Schema that checks them. A brand-new schema would be one more format for every journal and tool to learn, and it would drift away from the standards archives already read.
The one thing none of the four says is which file makes which table and figure. The profile adds that as an RO-Crate entry, and nothing else.
What would show this claim is wrong
Claim: recommendation
Most reviewers don't have days to rebuild an analysis. Automation can help, if it's built in the right order. I recommend three layers. First, rules a program can check without judgment: is the release archived, are the software versions pinned, does the data DOI resolve, is there one entry point, are the outputs declared. Each rule answers yes, no or cannot tell. Second, a model, used only where a rule can't answer, such as finding the steps in a README that never names an entry point; it says where in the repository it looked. Last, a person, who judges what the first two layers flagged. A lower layer's answer is never overruled by a higher one.
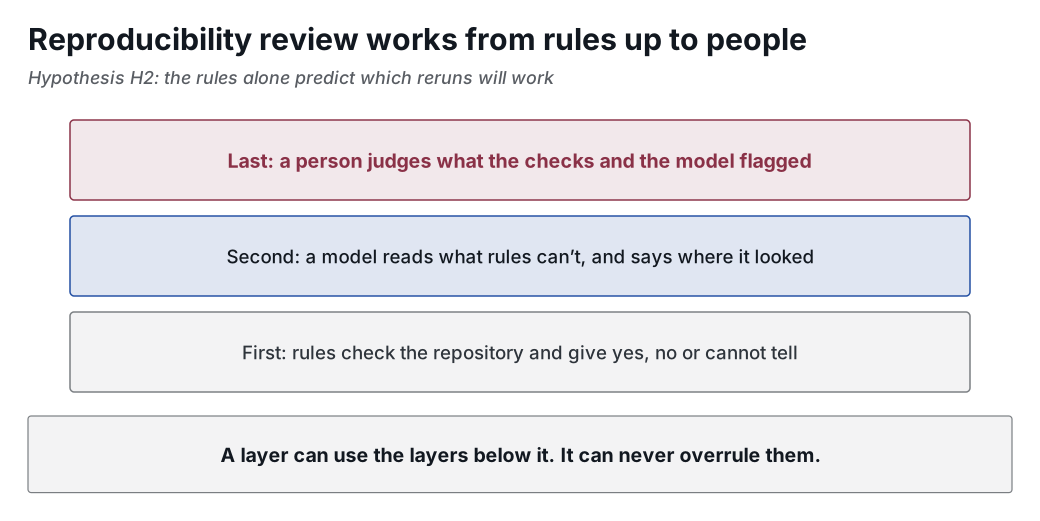
Instead of reconstructing a pipeline by hand, a reviewer gets a report: which checks passed, which outputs the rerun reached, where it stopped, and what the model flagged and why. The reviewer's time goes to the findings, not the plumbing. The reasoning, and why the order matters, is in Check reproducibility with rules first, a model second and a person last. The same ordering is what Evidence Credibility Engineering recommends for judging research in general.
What would show this claim is wrong
Claim: evidence
Sources: the NIH Policy for Data Management and Sharing (NOT-OD-21-013) and its plan elements (NOT-OD-21-014), Executive Order 14303, "Restoring Gold Standard Science" (90 FR 22601), CONSORT 2025, SPIRIT 2025, the FAIR principles for research software and the TRUST principles, read on 2026-10-22 (source-check.md).
The NIH policy took effect on 25 January 2023. It requires a plan for managing and sharing scientific data, and it doesn't ask anyone to share the code of an analysis; the plan only names the tools a person needs to use the shared data. The executive order, signed on 23 May 2025, defines Gold Standard Science as reproducible, transparent and open to being proved wrong, among other things, and tells federal agencies, "to the extent practicable", to make public the analyses behind influential science, "including, as applicable, the source code". It binds agencies, not the researchers they fund. CONSORT 2025 and SPIRIT 2025, the reporting guidelines for clinical trials, ask authors to say where the statistical code can be found; they don't require sharing it. NIH published a plan for Gold Standard Science on 22 August 2025, which I couldn't open, so I say nothing here about what it asks of code.
A companion repository fits all of these and is required by none of them.
| Policy or principle | What it asks for | Where a companion repository fits |
|---|---|---|
| NIH Data Management and Sharing Policy | A plan, and shared scientific data | Adds the code that turns the shared data into the paper's results, which the policy doesn't ask for |
| Executive Order 14303 | Agencies make influential analyses public, with source code where applicable | Gives an agency, or a grantee it funds, the code in a form that can be rerun |
| CONSORT 2025 and SPIRIT 2025 | Trial reports say where the statistical code can be accessed | Gives that statement a permanent address with a DOI |
| FAIR principles for research software | Code that is findable, accessible, interoperable and reusable | The six parts and the metadata profile make a paper's code meet them |
| TRUST principles | Repositories that are transparent, responsible, user-focused, sustainable and technically sound | Applies to the archive that holds the release, such as Zenodo or Software Heritage |
| Institutional policy and data use agreements | Whatever the institution and the data owner require | Comes first, every time |
Claim: evidence
Sources: Stodden, Seiler and Ma, PNAS 2018, Price and colleagues, BMJ Open 2018 and the American Journal of Political Science verification policy, read on 2026-10-22 (source-check.md).
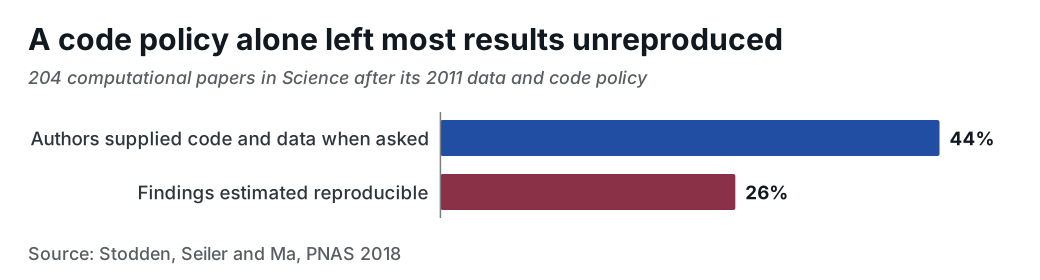
Stodden and colleagues asked the authors of 204 computational papers in Science, published after the journal's 2011 data and code policy, for their code and data. They got them for 44% of papers and estimated that the findings of 26% could be reproduced.
A survey of reviewers at 17 BMJ journals found that 95% said they had seen supplementary material at least sometimes, which says what they saw and not what they checked. I found no study that measures whether peer reviewers open or run the code they're given. The American Journal of Political Science makes publication depend on a successful rerun, and specialists at two data archives do that work, not the peer reviewers. Asking for code isn't the same as rerunning it, and where rerunning happens it's a paid job.
Claim: evidence
Sources: Kidwell and colleagues, PLOS Biology 2016, Maitner and colleagues, Ecology and Evolution 2024 and Heumüller and colleagues, Empirical Software Engineering 2020, read on 2026-10-22 (source-check.md).
After Psychological Science started giving badges for open practices, the share of its articles reporting open data rose from about 2.5% to 22.8%, while comparison journals stayed near 3%. That study didn't measure citations. Of 1,001 ecology and evolution papers that cite R, about 6% shared code, and those papers gathered citations faster. In 789 software engineering conference papers, linking to the software had a small positive link with citations. All three are observational: papers that share code may differ in other ways that bring citations, so none shows that sharing causes them, and none is from biomedical research. Badges, featured placement and credit in grant reviews are reasonable incentives to try; whether they raise citations in medicine is not known.
Claim: evidence
Sources: CodeMeta, the Citation File Format, RO-Crate 1.3, the DataCite Metadata Schema 4.7 and Zenodo's versioning help, read on 2026-10-22 (source-check.md).
CodeMeta, now at version 4.0, describes software in a codemeta.json file. The Citation File Format, at 1.2.0, says how to cite it in a CITATION.cff file. RO-Crate 1.3, published in June 2026, packages data, code and the links between them. The DataCite schema 4.7, from March 2026, describes the DOI record and now accepts a Software Heritage identifier. Zenodo gives each archived GitHub release its own DOI and a concept DOI for all versions. None of them states which file makes which table and figure, which is the part a rerun needs most.
Claim: hypothesis
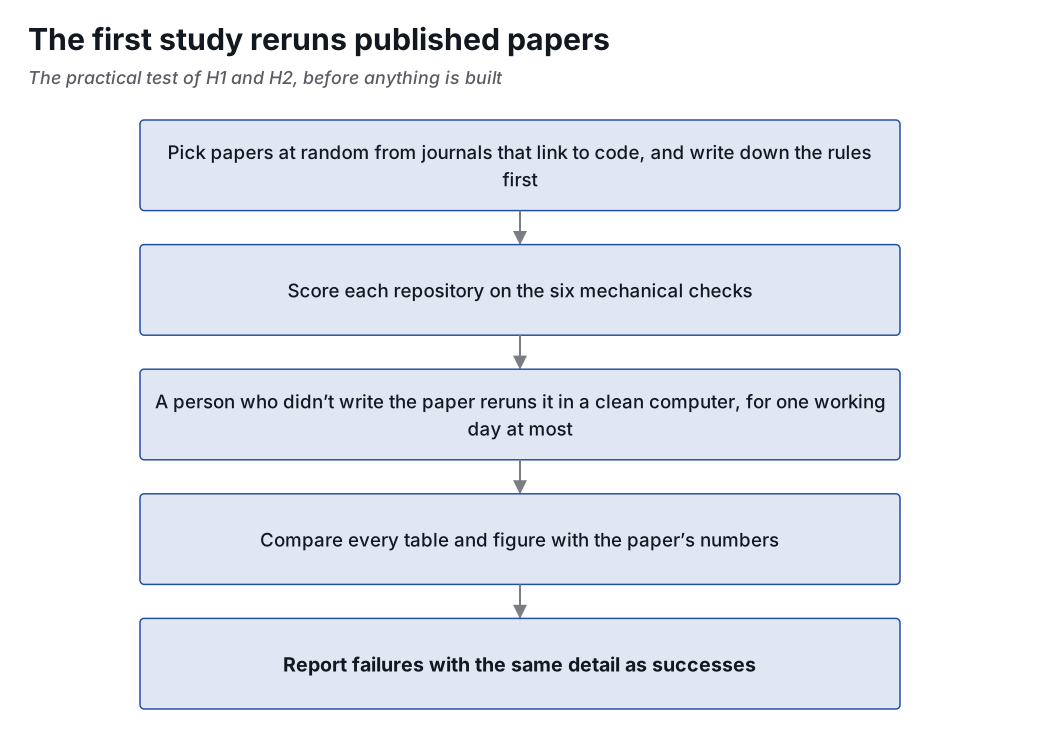
Practical test: Take a random sample of papers in diabetes technology and biomedical journals that link to code. A person who didn't write each paper follows the rerun protocol in the companion. Measure how many reach the paper's numbers within one working day, how long each takes, and why each failure happened. If more than half reach the reported numbers, H1 fails.
Claim: hypothesis
Practical test: Before the reruns in H1, score each repository on the rules a program can check without judgment: archived with a DOI, software versions pinned, data DOI resolves, one entry point, outputs declared. Compare the scores with the rerun results. If the checks separate the reruns that work from those that don't no better than chance, H2 fails.
Claim: hypothesis
Practical test: Ask research groups to log the hours they spend making a companion repository for each of their next three papers, using the author checklist in the companion. If the third takes as long as the first, H3 fails, and the cost is a standing cost per paper that someone has to fund.
Claim: hypothesis
Practical test: Give matched reviewers the same papers, half with a companion repository that reruns and half without, and plant known errors in some of the analyses. Measure how many planted errors each group finds and how long it takes. If both groups find the same share, H4 fails.
Claim: recommendation
Research groups make companion repositories, so the program starts with them. Everyone else reads them, and each gets a different thing.
I recommend that funders and diligence teams treat a project without a companion repository as unverified until the authors show the code that produced it, and that they ask for a rerun before any decision that depends on a number. That's a recommendation about how to read evidence, not a finding that projects without one are wrong.
What would show this claim is wrong
| Reader | What they get | Use case |
|---|---|---|
| Research groups and data managers | A record of every analysis decision, tied to the paper, that answers a reviewer's question with code that runs | A research group can answer reviewers by pointing to code that runs |
| Journal editors and reviewers | A rerun report with each submission, so review time goes to the findings | A journal can give reviewers a rerun report with each submission |
| Funders and program officers | Analyses they can compare across grants, and a rerun before a renewal | A funder can ask for a rerun before renewing a grant |
| Clinicians and guideline writers | The exact definitions and thresholds behind a clinical finding, and how they held up on new data | A clinician can see exactly how a study defined its outcome |
| Industry and diligence teams | A finding they can rerun before they license it, invest in it or build on it | A diligence team can rerun a finding before licensing it |
Claim: unknown
Hosting public code on GitHub, GitLab or Zenodo costs a research group little or nothing. The real cost is time: the researcher's, to clean up, document and archive the code, and the reviewer's, to rerun it. I don't know how many hours either takes in this field, or whether journals, funders, institutions or the groups themselves would carry them. H3 measures the first part. The second needs a funder or a journal willing to pay for reruns on a small set of papers and report what it cost.
Claim: unknown
Services exist that package or run research code. Code Ocean bundles code with what it needs to run, and three Nature journals trialled it for code review in 2018. Binder builds a runnable environment from a repository. Whole Tale packages data, code and environment together. Software Heritage archives source code under an identifier that is now the standard ISO/IEC 18670. I haven't tested any of them against the six parts or the rerun protocol. If one of them already holds all six and reruns to the reported numbers on most biomedical papers, the program should narrow to what that service leaves out, or stop.
Claim: recommendation
I recommend starting with H1 and H2 together: a random sample of published papers in diabetes technology and nearby biomedical fields that link to code, each scored on the mechanical checks and then rerun by a person who didn't write it, using the protocol and result record in the companion. Success and failure are defined before the first rerun, and failed reruns are reported in the same detail as successful ones. Nothing is built for sale until this study shows what goes wrong and how often.
What would show this claim is wrong
A clinician deciding whether a study applies to their patients needs the exact definitions behind its conclusion: what counted as treatment response, which patients were left out, which thresholds were used. A companion repository shows them in the code that ran, with the data dictionary, and later releases show whether the finding held on new patients.
Setting up a companion code repository takes seven steps, and most research groups can do the first five in an afternoon once the analysis is finished. The steps go from storing the data in the right place to making the code rerun on new data, and the last one, automated checking, is optional.
Before a company licenses a biomarker, invests in a device or builds on a published result, its diligence team can rerun the analysis behind the finding. A companion repository, public or shared privately under an agreement, turns a judgment about the authors into a check of the method.
A funder or program officer deciding whether to renew a grant usually reads the progress report and the papers. With companion repositories, the funder can also see the actual analysis pipelines, compare methods across the grants in a portfolio, and ask for a rerun of the result the renewal depends on.
A journal editor can ask authors to submit a companion repository with the paper, run automated checks and a rerun before review, and hand reviewers a short report: what ran, what matched the paper's numbers, and what was flagged. Reviewers spend their time on the science, and the journal can mark papers whose results rerun.
Code that can't be public, because of a patent plan, a contract or commercial value, can still be checked. Keep the companion repository private and invite the editor, the reviewers or the funder you choose. Software companies protect their code this way every day.
When evidence is thin or can't be checked, medicine leans on who said it: the senior author, the famous journal, the expert panel. When anyone can rerun the analysis and test it on new data, the question shifts from who said it to what the evidence keeps showing.
A research team can publish a companion repository with its paper. When a reviewer asks how a number was produced, the answer is a release that reruns it. The team gets a citable software record, a precise history of every analysis decision, and a way to update the method as new data arrives.
Most peer reviewers can't spend days rebuilding an analysis. Automation can take that load, but only if it's built in the right order: rules that a program checks without judgment first, a model only for what rules can't answer, and a person last. A higher layer never overrules a lower one.
Split a study's materials by risk: data about individual patients goes to a repository built to control access to it, and everything else, the code, the metadata and any data with no patients in it, goes in the companion repository beside the paper. The split puts the governance burden only where the risk is.
Many published analyses were done in a spreadsheet, not in code. That's fine: a spreadsheet with its formulas intact, its data in open formats and a short README that says the order of the steps is a companion repository too.
A published paper is a snapshot. A companion repository can keep going: each time the same method runs on new real-world data, the authors publish a new release with its own DOI, and the release the paper cites never changes. Peer review keeps its job, and readers can see whether a finding still holds.